

Normalize your API responses: the refactor that pays for itself
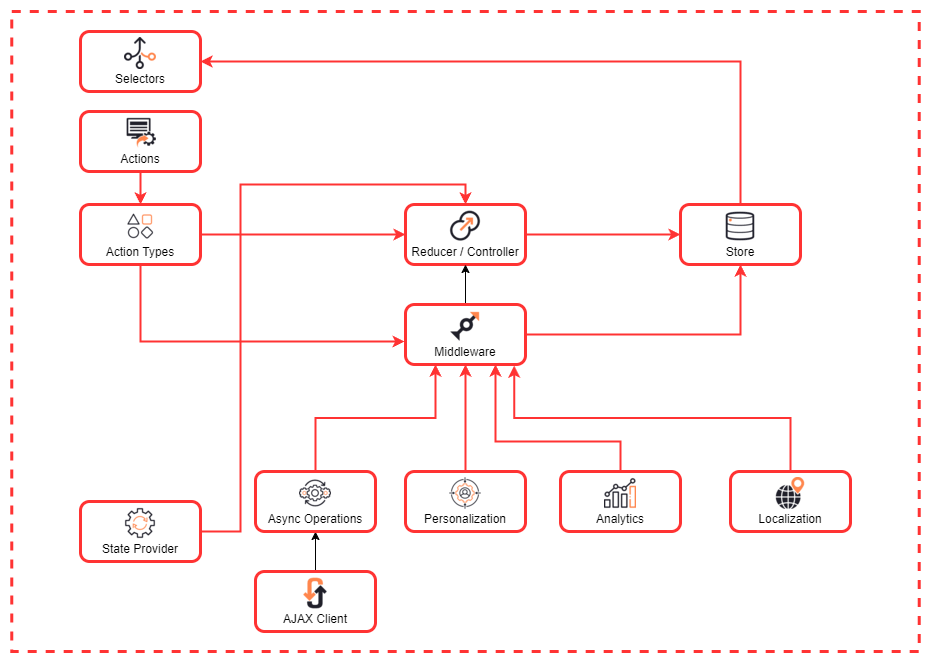
APIs return data shaped for transport: deeply nested, with the same entity duplicated wherever it is referenced. A list of posts each carries its author object; the same author appears in ten posts. If you store that payload in your state as-is, every one of those copies is now a fact you have to keep in sync, and updating an author’s name means finding and editing ten nested objects. The fix is normalization: flatten the nesting into flat tables keyed by id, exactly like a relational database. It is the one state refactor that reliably makes everything downstream simpler.
The shape: byId plus allIds
The normalised form for a collection is two parts: a byId map for O(1) lookup by
id, and an allIds array to preserve order and let you iterate. A transform turns
the API’s array into this shape:
function normalize(posts) {
  const byId = {};
  const allIds = [];
  for (const post of posts) {
    byId[post.id] = post;      // keyed lookup
    allIds.push(post.id);      // ordered list
  }
  return { byId, allIds };
}
// { byId: { 1: {...}, 2: {...} }, allIds: [1, 2] }
Nested relationships get the same treatment: pull the authors into their own
users.byId table and replace each post’s embedded author with an authorId.
Reads and updates both get cheaper
With byId, looking up a post is state.posts.byId[id] — no .find() scan of an
array. And updating an entity touches exactly one place, immutably, without
walking a nested tree:
// update one user's name — one entry, no matter how many posts reference them
case "USER_RENAMED":
  return {
    ...state,
    users: {
      ...state.users,
      byId: { ...state.users.byId, [action.id]: {
        ...state.users.byId[action.id], name: action.name,
      }},
    },
  };
Every post that references authorId: 7 now reads the new name automatically,
because there was only ever one copy.
Rehydrate the shape with selectors
The nested shape was convenient for rendering, and you do not lose it — you
derive it back with a selector at read time, joining the tables. A memoized
selector recombines posts with their users only when either table changes, so
the join is cheap and the stored state stays flat:
const selectPostsWithAuthors = createSelector(
  [(s) => s.posts.allIds, (s) => s.posts.byId, (s) => s.users.byId],
  (ids, posts, users) =>
    ids.map((id) => ({ ...posts[id], author: users[posts[id].authorId] }))
);
This is the same principle behind a database’s normal forms: store each fact once,
join on read. Normalisation front-loads a little transform code and pays it back
on every update you no longer have to duplicate and every list scan you turn into
a keyed lookup. The normalize-entities exercise builds the byId/allIds
transform and the selector join, which is the whole pattern in miniature.